I wrote the following as extra credit for my civil procedure class as an example of how provisional relief is used in the real world, specifically in the ongoing litigation around college athletics. This comes right as Congress is in the process of reversing the Supreme Court in order to roll back one the biggest labor victories of the past decade.
I'm quite proud of what I submitted (I wrote twice the required length), so I'm sharing it here in the original form I turned it in in.
Historically the National Collegiate Athletic Association (NCAA) put a significant emphasis on players being amateurs: playing for the love of the game and not money. Meanwhile, coaches and administrators raked in billions off the backs of unpaid athletes, who never saw a dime. The courts have finally started to catch up with this crisis; the Supreme Court unanimously ruled in NCAA v. Alston (2021) that the NCAA’s restrictions against athletes from profiting off of their own name, image, likeness (NIL) was a violation of antitrust law. Justice Kavanaugh took it one step further in his concurrence, writing, “Nowhere else in America can businesses get away with agreeing not to pay their workers a fair market rate on the theory that their product is defined by not paying their workers a fair market rate. And under ordinary principles of antitrust law, it is not evident why college sports should be any different. The NCAA is not above the law.” And lawyers all across the country have taken his words to heart, beating the NCAA in just about every major court case since.
Fast-forward to 2024, many college football players are being paid through the guise of NIL – in some cases earning generational wealth in a few years. So now plenty of other people want in on the money, setting up a legal battle over the NCAA’s previously ironclad eligibility rules. In short, athletes have four years of eligibility, but once you go pro (e.g. NFL, NBA) you can’t come back to NCAA sports.
In 2024, Vanderbilt quarterback Diego Pavia sued the NCAA under the Sherman Antitrust Act, saying that the year he played football at a junior college shouldn’t count towards his eligibility because it limited his ability to profit in Division I football. He asked for a preliminary injunction to prevent the NCAA from enforcing its rules against him. Ruling in favor of Pavia, the judge walked through the same standards we learned in class: 1) likelihood of success on the merits: plaintiffs appear to meet the criteria the Supreme Court laid out in Alston, 2) irreparable harm: many courts have found that being unable to play sports is irreparable harm 3) balance of equities & public interest: it’s narrow towards Pavia only, and the public wants free and fair markets. (The judge combined parts 3 and 4 into one analysis step.) The motion for an injunction ended up being the entire battle, as the NCAA granted all junior college athletes an eligibility waiver, leading to the dismissal of Pavia’s case for mootness.
In 2025, the House v. NCAA settlement was finalized, allowing colleges to directly pay athletes through revenue-sharing. The next fight over eligibility was for people who technically went pro, but didn’t properly make it, so they wanted to come back to college to earn a stable income (and presumably also to study).
Despite having previously signed an NBA contract, former University of Alabama basketball player Charles Bediako tried to make a comeback, and sued the NCAA in early 2026 after they denied his eligibility. In state court, Bediako won a temporary restraining order for 10 days, allowing him to play. Five games later, the same judge – an Alabama alumnus – reversed his position, denying Bediako’s motion for a preliminary injunction. Bediako’s situation illustrates the different circumstances between temporary restraining orders and preliminary injunctions.
Right as we were discussing provisional relief in class, two former University of Mississippi football players, who signed pro contracts and participated in NFL training camps, attempted to play at LSU with their former coach. A Louisiana state judge granted them a temporary restraining order against the NCAA from enforcing eligibility rules on August 19th. The Southeastern Conference (SEC), of which Mississippi, Alabama, and LSU are all members, then passed a policy banning former professional players. The players responded by filing for and receiving an expanded temporary restraining order that covered the SEC too on August 28th. After a hearing, the judge granted them a preliminary injunction on September 3th – two days before LSU’s first game on the 5th. Unhappy with the outcome, the NCAA and SEC filed suit in federal court asking for their own injunctions. As best I can tell, that litigation is still pending, but it may be moot. Multiple opponents threatened to cancel their games with LSU, and the rest of the SEC threatened to kick LSU out of the conference entirely, so in the end, the coach didn't add either player to the final roster despite both of them thoroughly winning in court.
To some extent this whole situation is ridiculous, you can’t run a coherent sports league when random state judges – often alumni of the school in question – are issuing temporary restraining orders and preliminary injunctions and then flip-flopping each week. The NCAA also appears to not be interested in letting cases actually get decided on the merits to avoid the risk of losing. Instead it’s taken its case to Congress, which is working on a “Protect College Sports Act” to take away legal victories from athletes and “protect” coaches’ and universities’ profits.
SecureDrop uses Qubes OS to power its next-generation journalist workstation because of its strong security properties. Over the years we have developed a good working relationship with the Qubes team, including financially supporting development in a way that benefits all Qubes users. At the same time, SecureDrop has also benefited from improvements in Qubes that we never thought to ask for or could imagine. Instead of fearing the churn and busy work caused by major Qubes upgrades, we look forward to them because we get a new set of features that make our lives easier.
After briefly introducing the SecureDrop Workstation for context, this talk will cover a number of features that the SecureDrop team asked for and/or financially supported, as well as features that Qubes introduced independently that benefited us. Some of these are big headline features, while others are small, niche ones. For example, we had a long running task to introduce per-source dispVMs to avoid journalists having to wait for a dispVM to launch, which was resolved by the introduction of preloaded dispVMs. Or the introduction of QubesDB’s vm-config, which allowed us to dramatically simplify our provisioning and configuration logic while improving our security posture through dispVM adoption.
Finally the talk will conclude with a small wishlist of upstream improvements we’d love to see and what we hope to accomplish next.
The talk is scheduled for 11:20am CET / 6:20am EST on Oct. 30, 2026; it should be recorded and likely livestreamed too.
I have forked the rocket_dyn_templates crate into a new rocket_tera one. I believe the approach I've settled on will be better for both users and make it easier to maintain long-term.
rocket_dyn_templates provides integration between the Rocket web server framework, and three different templating libraries: tera, handlebars, and minijinja. When I initially started working on Rust projects, I picked Rocket because of its similarity to Flask, and Tera because of its similarity to jinja (at the time minijinja wasn't supported).
Rocket is un(der)maintained, to say the least. For me at least this hasn't been a major issue and honestly I appreciate there isn't a giant amount of churn in the ecosystem.
tera 2.0 came out in June, and it has a lot of features I want, specifically: much better validation and components. I don't expect for rocket_dyn_templates to get updated for it anytime soon, so I've forked it into rocket_tera.
As the name implies, this new crate only supports tera templates. I don't use handlebars or minijinja, and am not interested in maintaining such functionality.
Plus I think slimming it down will make it easier to maintain by reducing the scope, at the cost of a little bit of duplication when someone else inevitably makes rocket_handlebars and rocket_minijinja crates.
My goal is to just keep the existing shape of the crate while keeping it up to date with upstream releases.
I've tried to make migrating as straightforward as possible with a pretty minimal set of changes. Upgrading is a two-step process and documented in UPGRADING.md.
In v1, all of the handlebars/minijinja code has been removed, which allows for some API simplification. Notably, templates no longer need a *.tera extension, because we now know that all templates are tera :)
v2 is primarily upgrading from tera v1 to v2, which has its own migration guide. A number of upstream filters and functions were moved to a new tera_contrib crate, so there are features in rocket_tera to seamlessly make it work.
Note: I have only issued RC releases for both, 1.0.0-rc3 and 2.0.0-rc2; I'll wait about a week for any feedback and then cut stable releases.
In February when English Wikipedia (and a few months later, all of Wikimedia) banned usage of archive.today (aka archive.is), there was a bit of a crisis in needing to find alternative archives.
For reasons, archive.today was especially good at archiving some difficult websites that weren't available in the Wayback Machine. I know a lot of people used it to bypass paywalls, and for related or unrelated reasons, there was an FBI investigation into the site.
Wikipedia editors have started discussing what a better solution to archiving webpages could be, with much of the discussion focusing on copyright.
As far as I know, no solution has actually materialized, so I thought I'd at least write down my idea. I am not actually planning to implement this, so feel free to steal this idea, my only ask is that you give it a hella sick name.
Unlike most other archives I know of, I would have users upload the archived content. By treating the archives as user-generated content, we get to take advantage of a number of legal protections, like Section 230 in the U.S.
Editors would install a browser extension that when asked, would capture a WARC (or similar) of the URL, and then upload it to the archive. It would be nice if there's some cryptographic way to verify the request wasn't tampered with (e.g. looking at the TLS connection?) but even without that, uploads would still be associated with specific editors, so if someone was caught falsifying, we'd be able to track it, just like you would deal with on Wikipedia.
This also conviently works around the drastic increase in scraper blockers that have started to lock down the internet by doing it in the user's browser. For some very dynamic content, we might also want to capture a screenshot, so if it relies on some complex JS or APIs, we can at least display what it looked like.
The biggest change would be that editors need to annotate specifically which part of the webpage is being cited. I think this is a good practice for citations in general.
But because we'd only publicly display the limited snippet, it would work around the archive being used to bypass paywalls. Displaying a limited amount greatly works in our favor for a fair use claim; to quote Wikipedia:
In general, the less that is used in relation to the whole, the more likely the use will be considered fair.
We'd need to develop some system to keep these snippets in sync with the on-wiki citations; I don't imagine it would be that complex to figure out.
While the snippets are sufficient for readers, editors might want to reference back to the full text for the purpose of expanding an article or just doing a more thorough fact check. I think we can still discourage the paywall bypass use-case by requiring editors to pay a small fee for access.
But instead of charging money, editors can pay with Wikipedia edits, e.g. 5 edits per URL. I think this would provide a small bit of friction that editors would only use it when they actually need it, but not enough to actually stop someone who genuinely needs access.
And of course if someone did choose to "game the system" to use it to bypass paywalls, they'd only be able to do so by actually contributing to Wikipedia, so... still a win.
I think it's quite difficult to launch a new site that accepts user-generated content, since you need to have a plan for content moderation. By building a Wikipedia-focused archive, we can piggyback on the existing Wikipedia community processes to help with this.
If you get blocked on Wikipedia, then you're blocked on the archive too. Have advanced administrator permissions on Wikipedia? We can automatically give you extra permissions on the archive. And so on.
I'm not sure if that would be sufficient long-term or just a temporary thing to help while it bootstraps and gets established.
I think the social and legal parts of this are far harder to get right; in comparison the technology seems pretty straightforward. I think it would be beneficial to have this be a separate LLC (i.e. not part of the Wikimedia Foundation) to isolate risk and allow for more flexibility.
While I think I've covered the primary legal bases, IANALY of course, it's entirely possible I've missed something. This is also a rather conservative proposal, and may have the consequence of shifting legal risk from the archive to individual users (though arguably that's how Wikipedia is already set up).
There are probably refinements to be made, or if you think I'm totally off, please, pitch your own proposal!
As part of Boba Quest 🧋, I'm trying and reviewing a new boba shop each week whenever I have time.
After nearly seven years of conducting boba reviews, I have built up a decent ability to predict if the boba will be good or not. I will always get a drink so I'm not merely judging a book by its cover, but it's rare that I'm surprised.
The Alley in Montreal genuinely surprised me with its excellent boba tea. From the very first sip, I could tell this wasn't merely good boba, it was fantastic.
(Admittedly, I mostly picked this place because the anonymous Montrealer had declared it the king of Montreal boba...so it's really on me for being shocked at how good it was.)
Just two blocks over from my previous review, The Alley is right next to the Green Line's Guy–Concordia station. There used to be a New York City location that opened in 2019, but best I can tell, it's since closed down.
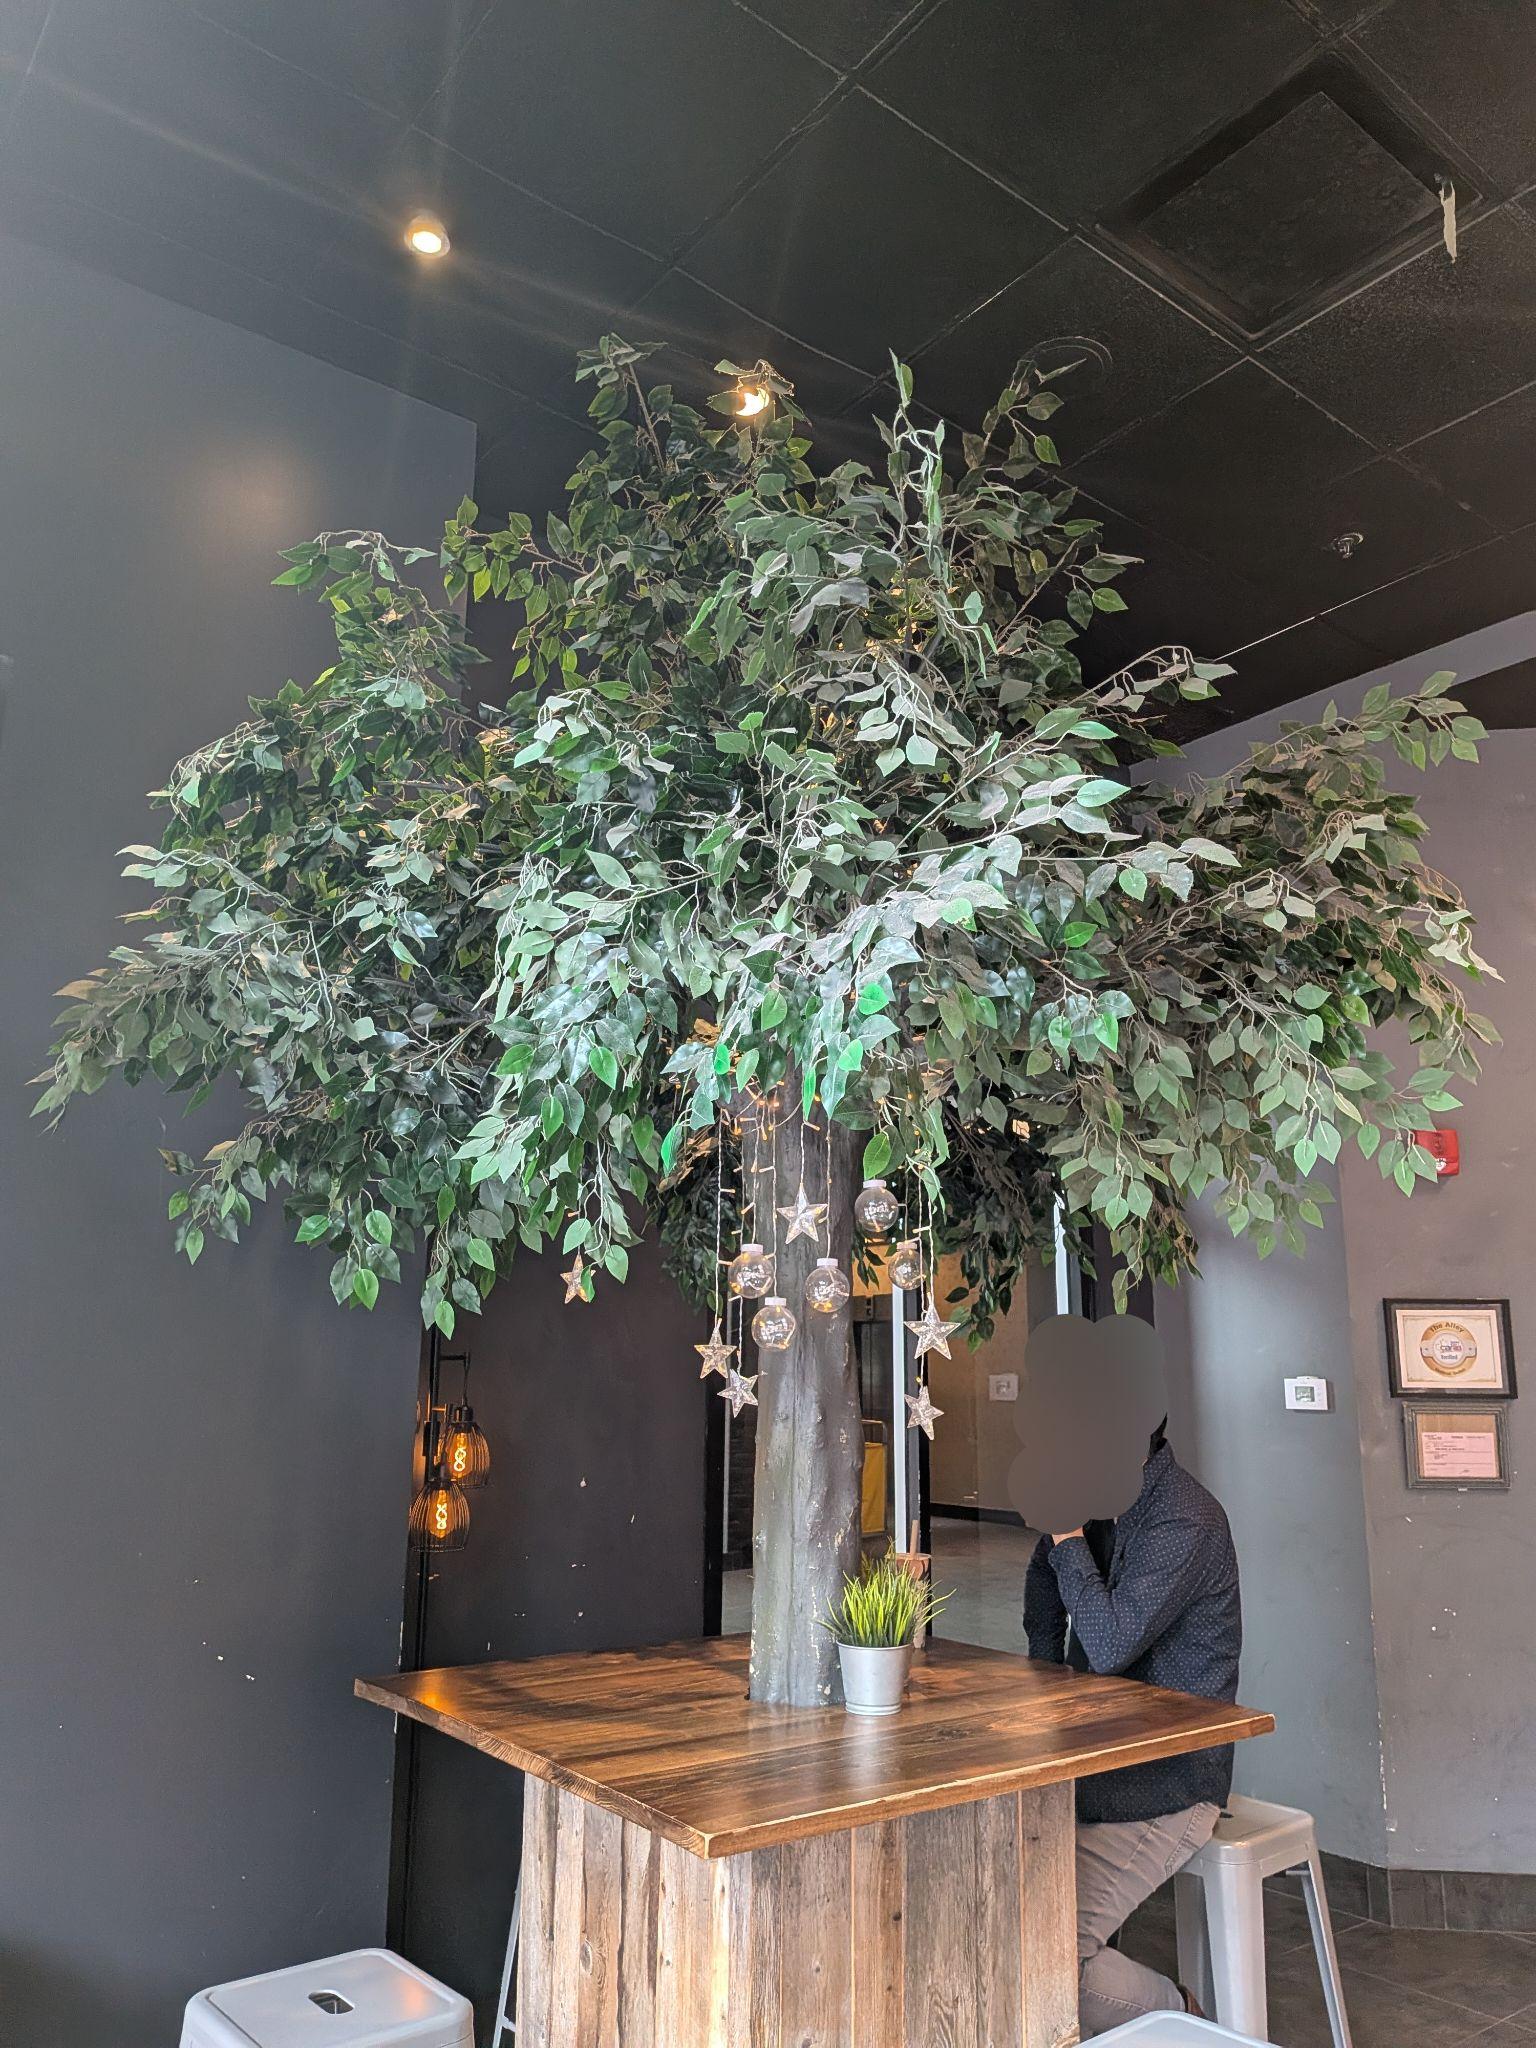
First boba shop I've been to with an indoor tree.
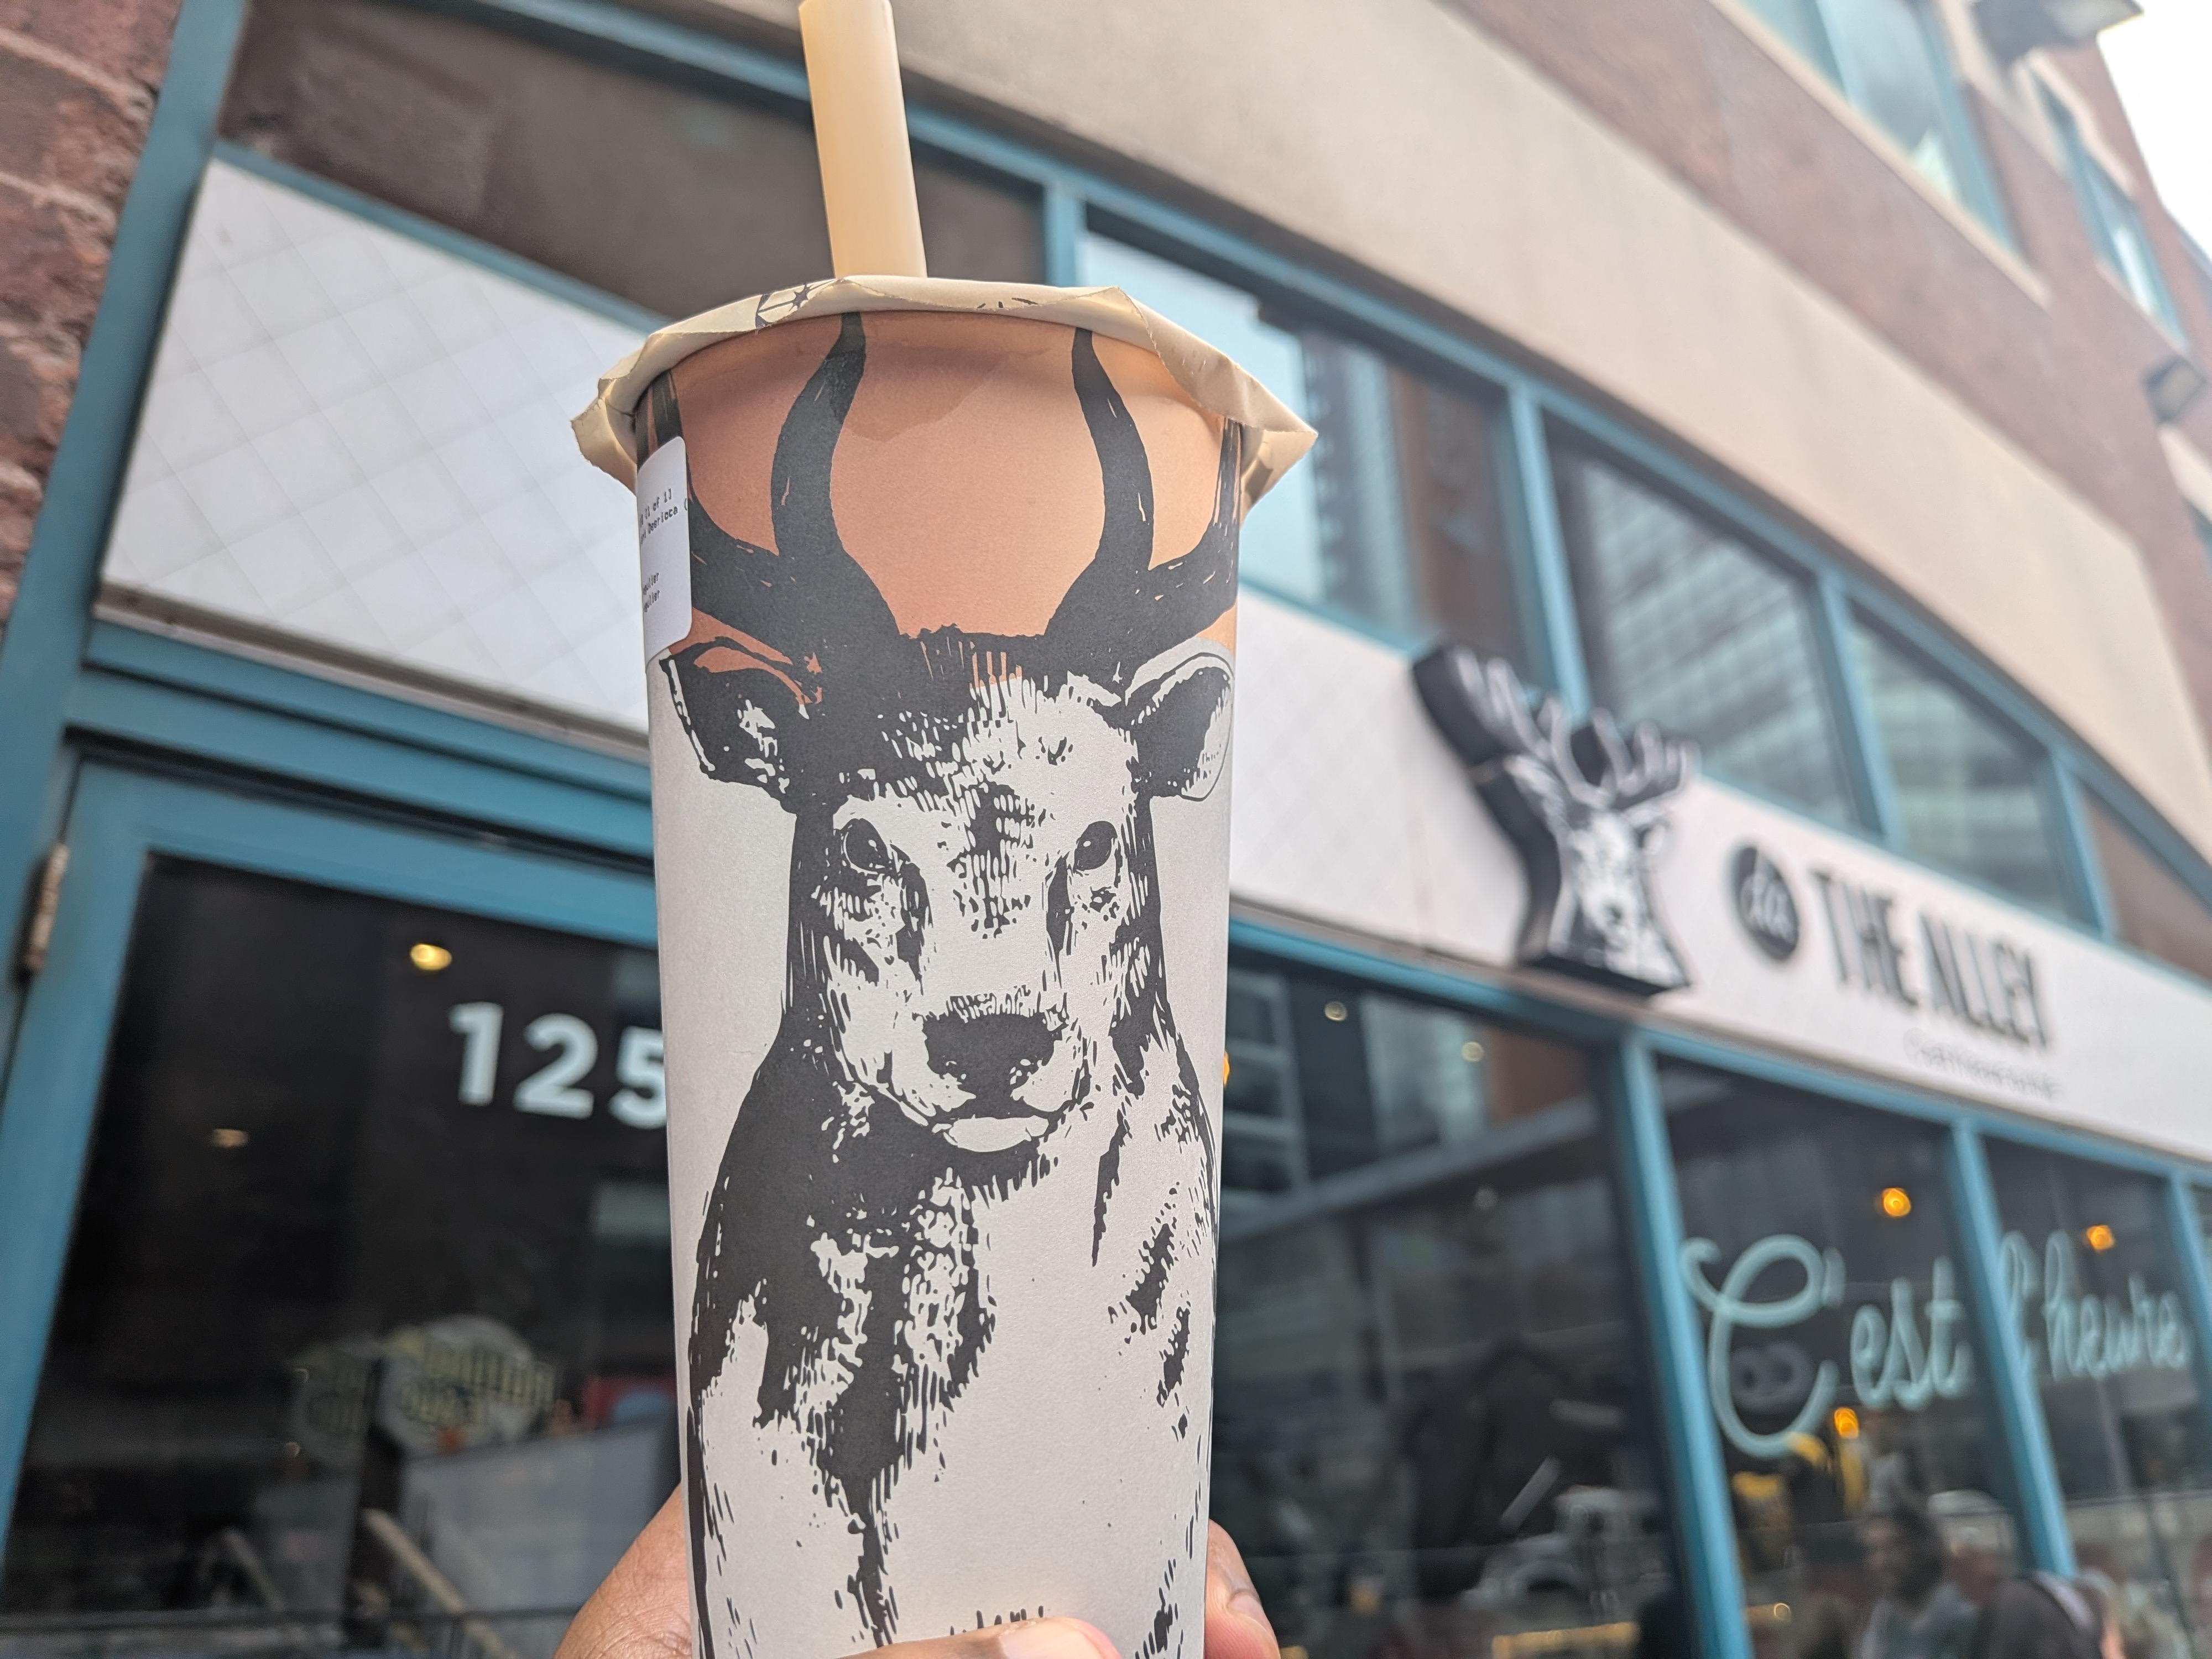
I ordered the Passionnément Deerioca (the menu was in French!), which is what they call their brown sugar milk tea with boba. I was not asked about my preferred sugar or ice levels.
Boba: 4/4 just perfection. Nicely sweet and exactly the correct chewiness. My first thought was that I had clearly forgotten how good boba could be and should probably downgrade some other places' scores.
Tea: 4/4 excellent; it melded smoothly with the boba without overpowering it.
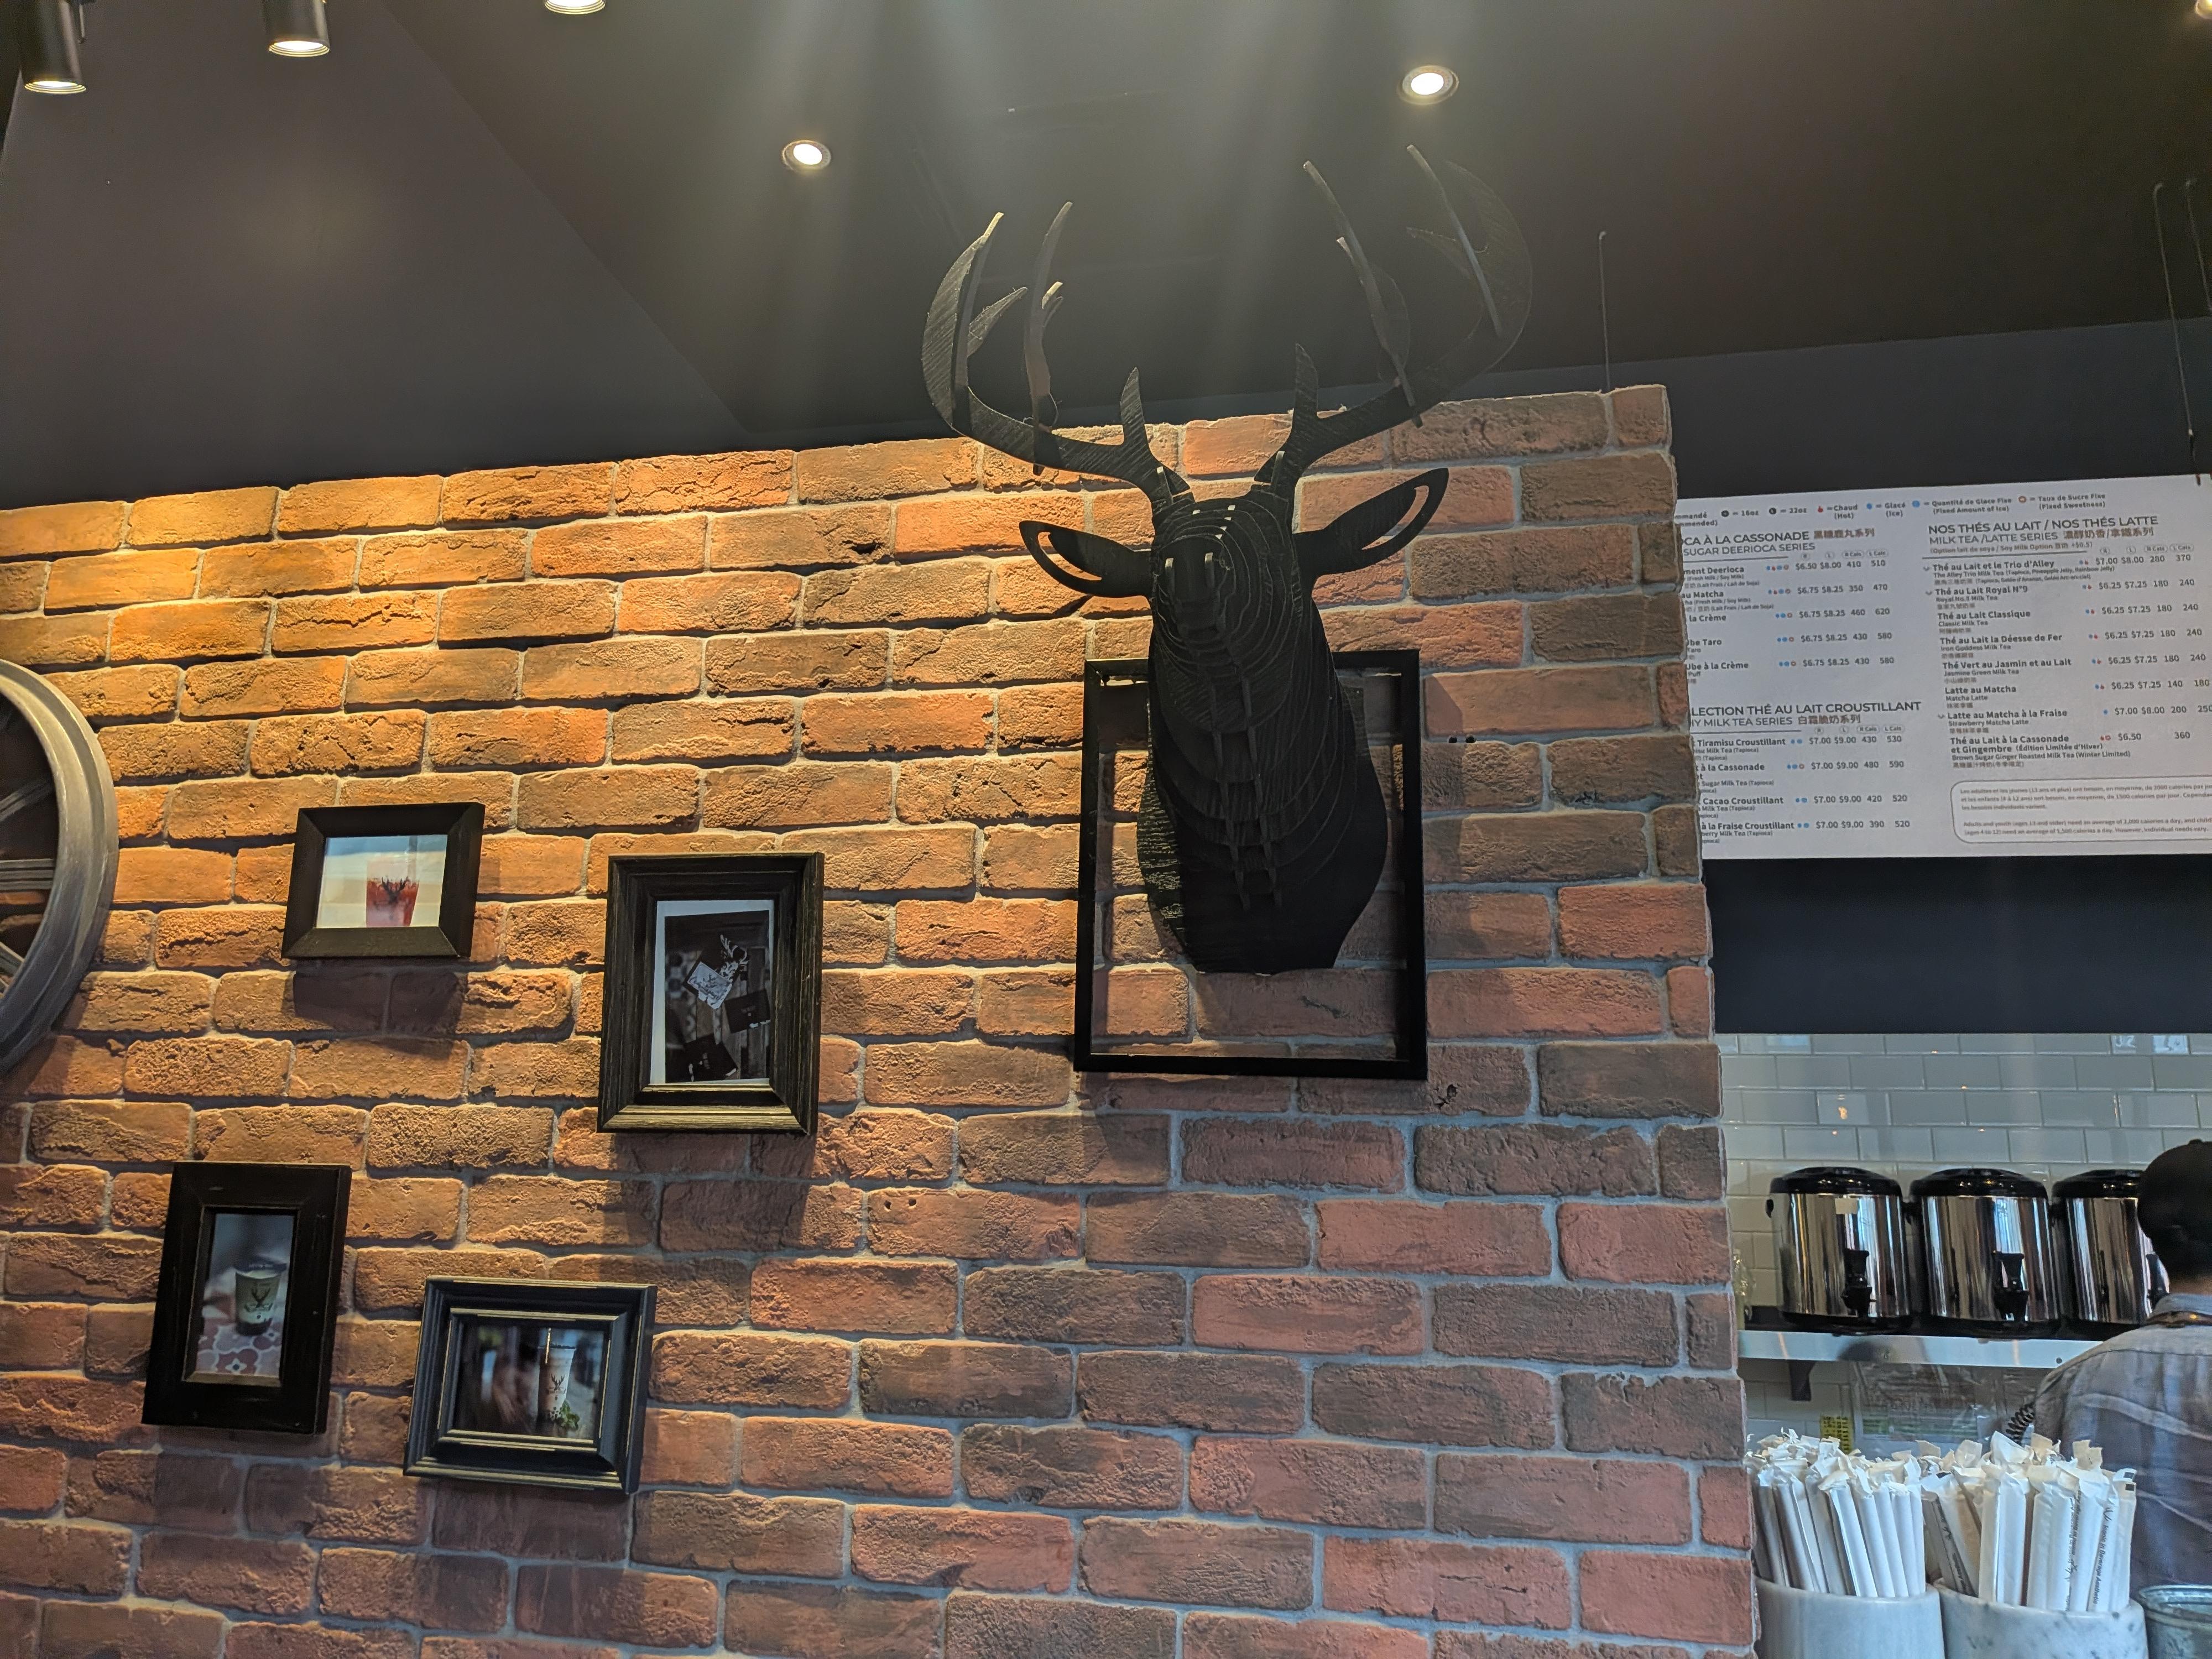
Bonus: 1/1 the atmosphere in the store was really nice (there's even a tree inside!), I would've stuck around for longer if I had the time. I appreciated the deer iconography, I was initially quite impressed at how Canadian it all seemed (spoiler: it is not).
Total: 9/10. For those keeping track, The Alley is the fourth boba shop to earn a complete score. Whenever I'm next in Montreal, I'll make sure to visit again to see if it can earn the coveted tenth point for consistency.
About those deer...
The Alley is a Taiwanese chain, and the deer are also Taiwanese and endangered. TIL that Taiwan has deer; my sources tell me that they're even on the currency in Taiwan.
I'm slightly disappointed that the deer theme wasn't a Canadian thing, but I can't complain with boba this good. 🇨🇦
The next alpha version, 0.2, of my "do-the-work" Git repository viewer is now available; you can try it out on git.legoktm.com.
My previous post explained the rationale behind it; in short: this viewer is entirely client-side, which means it takes very minimal server resources to host. The clickbait version of this headline would call it scraper-proof.
You can obtain the newly rebranded "gib" 0.2 (aka git-in-browser) from git.legoktm.com. A signed build for WEBCAT (more on this later) can be downloaded from GitHub.
I've written up a mostly complete changelog, the highlights are:
Render markdown files and images
Support downloading snapshots (tarballs)
Support downloading patches of commits
Display git notes
Rewrite names and email addresses per .mailmap
Support blame
Potentially faster git log lookups
Options to control how a diff looks
It's still nowhere near feature completion, but a lot closer to cgit. There was a lot of internal refactoring and in general just testing to verify behavior is as close to git as possible.
There is a little bit of performance work in this release, such as support for commit-graph, but for a number of operations it's quite bad on what I'd consider to be a medium-sized repository. For a personal git host with mostly small projects, it's efficient enough!
I would like for 0.3 to spend a lot more time on performance.
Git uses a forked version of the xdiff algorithm for diffs, patches, blame, etc.; a standalone build is available as part of the libgit2 project.
Best I can tell, no one has actually done a 1:1 port to Rust. GitOxide uses a forked version of imara-diff (which AIUI is slightly different but pretty close), and there's a separate crate that statically links to xdiff.
Turns out it was relatively straightforward to compile the C code to WebAssembly, so I too punted on a Rust port. Never thought I'd be so happy to use C code instead of Rust.
WEBCAT is a project by Freedom of the Press Foundation (where I work!) to verify the integrity of in-browser, client-side applications to ensure they haven't been tampered with by the host. For example, CryptPad would sign their build, so you could be confident that the random hosting provider you're using hasn't tampered with it.
This is intended to be used by a future version of SecureDrop, so I wanted to get more familiar with it. In theory gib is fully compliant with what WEBCAT needs, but it's still a little buggy.
But if someone else did set up another gib instance, and properly registered the domain with WEBCAT, you could automatically verify they haven't tampered with it. There isn't that much practical advantage to doing so, since the hoster could merely tamper with the Git repositories themselves, but hey, it's cool!
gib is currently ~38k lines of code; probably 10% of it (and shrinking) was written by hand. I would've never been able to build something like this by myself in such a short amount of time.
I've largely used this as my "how far can I push LLMs" experimentation project; it's been interesting and just a little bit addicting. I think it certainly helps that I'm trying to reimplement well known functionality in a very different backend stack, rather than coming up with something novel.
I spot check the code and ocassionally tweak things by hand; I think the code quality is not terrible? The comments I missed rewriting/cleaning up are usually quite bad.
Nothing, most likely. I worked on gib solely during vacation time, and now that school is starting up again, I would expect the project to go on hiatus.